360° feedback that finally
turns into action.
AI-first 360° feedback built on one agent, not another survey form. Atlas runs the whole cycle, grounds every line in evidence and turns every result into a development plan.
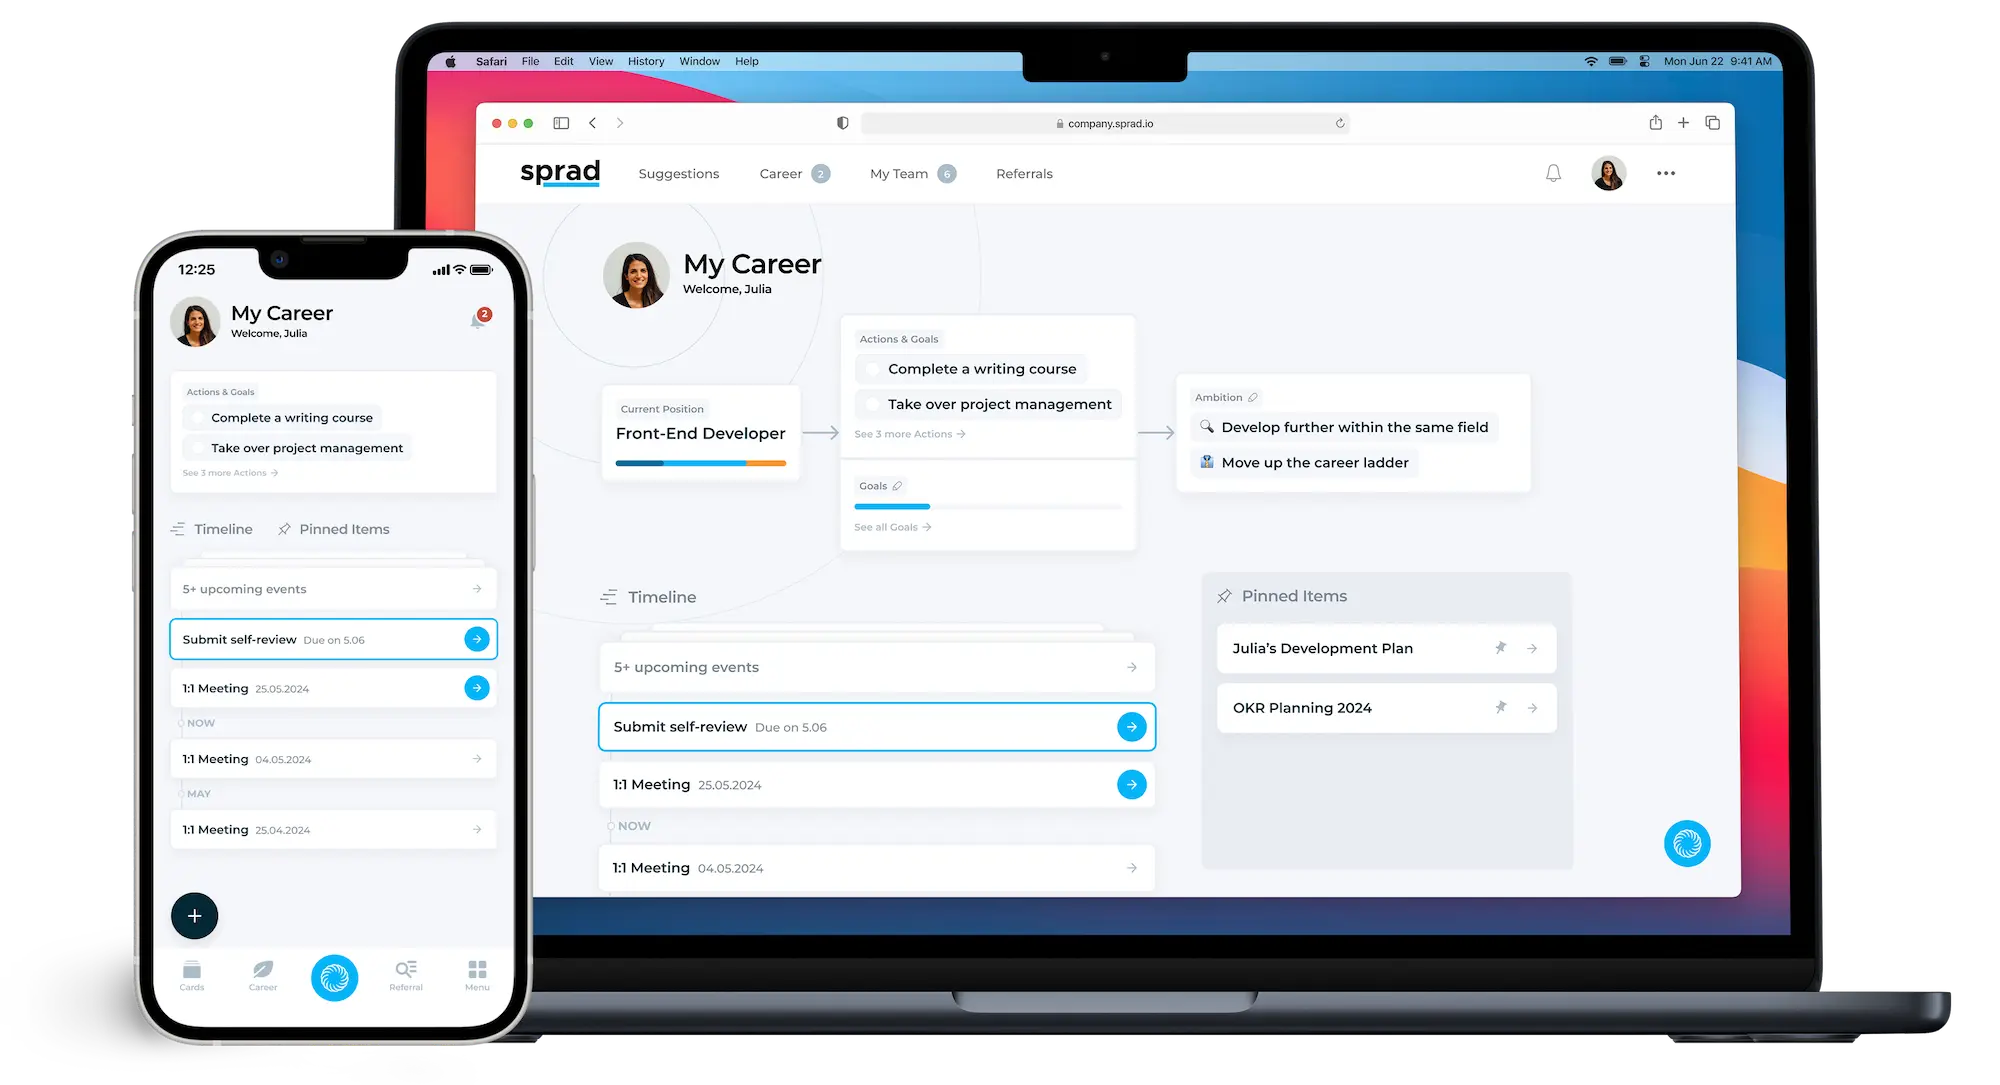
Everyone wants the feedback.
Nobody wants the cycle.
Weeks of coordination, ratings nobody quite trusts, and a report that lands in a folder.
The cycle eats three weeks.
Rater selection, reminders, chasing, compiling. Three weeks of coordination — none of it development.
Nobody trusts the ratings.
Every rater runs on a different scale, and 62% of a rating reflects the rater. 74% feel 360s are unfair.
The report ends in a folder.
A 360 that ends in a PDF changes nothing. No next step, no follow-through, no reason to run the next one.
One agent that runs the cycle, writes the report and turns it into a plan.
One page.
Not a thousand buttons.
One screen to give feedback, one to receive it — with Atlas drafting the wording from evidence it already has.

It ends in a plan,
not a PDF.
Every result turns into concrete next steps — in the same view as the conversation that follows.

The questions leadership
asks, already answered.
Cycles, themes and perception gaps in one place. Ask where perceptions diverge, get the answer with the evidence.

Anonymity built in,
not promised.
Peer and direct-report feedback stays anonymous by design. Results unlock only above the threshold you set — enforced by the system, not by an honour code.
You decide what stays anonymous and what is attributed, per rater group.
Calibrated
for fairness.
Some raters run hot, some run cold. Atlas normalises for rater bias so you compare people fairly — without losing the signal.
Questions are anchored in observable behaviour, not vague traits — so there is less bias to remove in the first place.
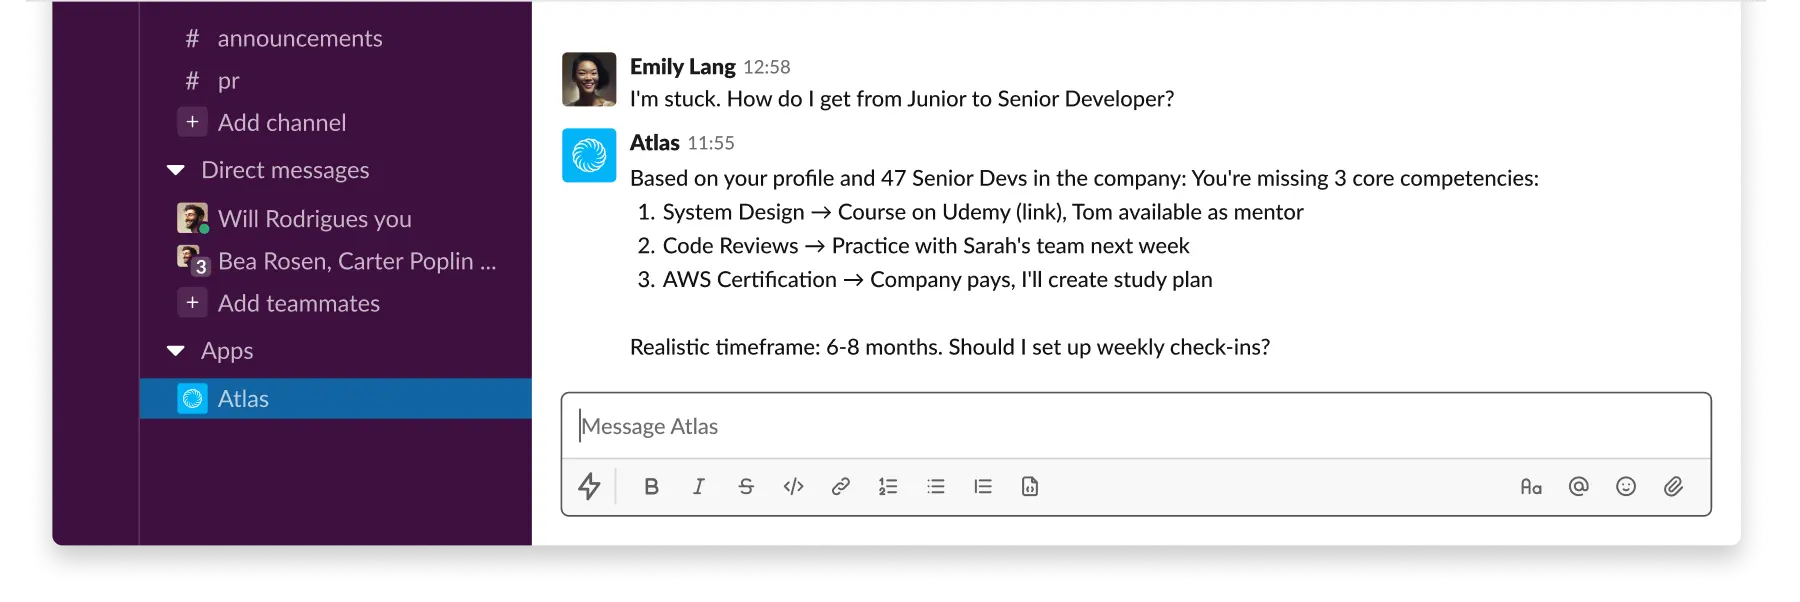
Coaching where your people already are.
Atlas turns each result into next steps and coaches the person in Slack or Teams — micro-coaching through the quarter, not a PDF once a year.
 Atlas · your AI agent
Set it once.
Atlas runs every cycle.
Rater nomination, reminder nudges, report synthesis, calibration prep, development plans — in the background, on a schedule or on a trigger.
 Discover Atlas →
Everyone you meet stays yours.
Sourced, applied, referred or hired — everyone keeps a living profile, with the score and the evidence still attached. The one you turn down in March is the one you search for in September.
 Ashby
 d.vinci
Part of the same system.
Feedback, performance and skills share one data model and one AI layer — so a 360 result sharpens the next review, and the review sharpens the skill profile.
Performance
Expectations, reviews and 1:1s — the 360 result flows straight into the next review.
See Performance →Skills
Behaviour-anchored questions come from your real skill framework — and the answers keep it current.
See Skill Management →Atlas AI Agent
The agent behind every module — it nominates, nudges, synthesises and coaches.
Discover Atlas →Questions, answered.
How many responses does it take before results are shown?
You set the threshold, and the system enforces it. Below it nothing unlocks — three responses is the common setting. Above it, results are shown and the raters stay anonymous.
Who picks the raters?
Atlas suggests the peers and reports based on your org and who the person actually works with. The manager approves — that is the whole step.
Can we compare people fairly if every rater scores differently?
That is what calibration is for. Atlas normalises for rater bias, so the comparison is about the person and not about who happened to score them.
Does it replace our HRIS?
No. Sprad docks onto the systems you already run and takes over the feedback and development work. Your system of record stays where it is.
How fast are we live?
Under 3 hours from signup to a running setup, with expert coaching included.
A cycle that ends in a plan.
360°, performance and skills — live in under 3 hours. No per-seat tax.