Candidate screening software checks applications against defined, job-related criteria before the first live interview. It reads resumes, runs structured chat or voice questions, tests skills, or combines these signals. The best tool is the one that shows the evidence behind every rating, so a recruiter can make and defend the decision. For resume review plus conversational pre-screening in one process with ATS write-back, Sprad Atlas fits best (reasons below); for developer tests, broad skills tests or pure frontline chat, a specialist is often leaner. Prices and legal dates: October 2026.
What is the best candidate screening software?
The best product depends on the signal missing from your first selection step. A team prioritizing many resumes against explicit requirements needs a different system from one evaluating coding ability, customer communication, or shift availability. Naming one universal winner would therefore be misleading.
Eight products stand out for a 2026 shortlist. They are not presented as an absolute ranking. The table maps each product to its strongest use case. In a detailed review, confirm that the provider supports your roles, languages, regions, and current applicant tracking system.
| Software | Screening method | Best suited to | Key limitation to test |
|---|---|---|---|
| Greenhouse Real Talent | ATS-native application review and matching | Greenhouse teams with high application volume | Its value is closely tied to the Greenhouse system |
| Metaview Application Review | AI-assisted resume review against a candidate profile | Teams seeking reasoned prioritization in their ATS | Document review does not replace skills or conversation evidence |
| Sprad Atlas | Evidence-linked resume review, chat and voice interviews | Teams combining resume evidence and conversation in their existing ATS | Not a test library; a broad process needs clearly defined criteria |
| TestGorilla | Skills tests, custom questions, and AI interviews | Broad job families and skills-based selection | Test length and job relevance require active design |
| HackerRank | Technical tasks and coding assessments | Software engineering and technical roles | Does not provide a complete view of nontechnical competencies |
| HireVue | Video, simulations, and several assessment types | Large, standardized selection programs | Implementation and validation may require substantial work |
| Paradox | Chat-based applications, screening, and scheduling | Mobile, high-volume frontline hiring | Complex suitability cannot be reduced to knockout questions |
| Willo | Asynchronous structured responses and assessments | Teams reviewing video, audio, or text responses later | The channel must fit the audience and accessibility needs |
What a screening model can realistically do — and where it stops — is covered in our piece on AI resume screening.
How we evaluated the software
The English search results are crowded with lists of features, prices, and broad ratings. German results often compare complete applicant tracking systems even though an ATS and a screening tool do not solve the same job. This review separates system administration from selection quality.
We did not score polished demos or invent an overall grade. How we compared: we read each provider's public product documentation, feature descriptions and price pages (as of October 2026) against these six questions; our description of Sprad comes from our own product. We did not run hands-on tests of the other products, so confirm every claim in your own pilot. Six questions matter, and each can be answered in a real pilot:
- Job relevance: Can every criterion be traced to the actual work?
- Evidence chain: Can recruiters move from a rating back to the answer, task, or source passage?
- Candidate journey: Is the step understandable, accessible, and supported by an equivalent alternative?
- Control: Do weighting, thresholds, approvals, and exceptions remain with your team?
- Integration: Do status, reasoning, and results return to the existing candidate record?
- Operations: Can recruiting and hiring teams maintain, audit, and update the process when the role changes?
Public prices in this category are rarely comparable. A price per test, interview, application, user, or contract reveals little without volume, implementation, and integration work. Ask every shortlisted vendor to quote the same pilot scope instead of placing unrelated list prices side by side.
1. Greenhouse Real Talent: screening inside the ATS
Greenhouse Real Talent organizes applications against job criteria defined by the recruiting team and shows why a profile was prioritized or flagged. It also includes fraud indicators and identity verification capabilities. For teams already using Greenhouse as their system of record, this approach removes an additional handoff.
It is less suitable when the real information gap appears after document review. Practical ability, motivation, or nuanced answers do not emerge simply because the application queue is sorted more effectively. Also test which information is usable only inside Greenhouse and how your team can correct false flags.
For the wider market view, see our category page on AI CV screening tools.
2. Metaview Application Review: reasoned resume prioritization
Metaview Application Review derives an ideal candidate profile from the job description and team input, reviews applications against it, and gives written reasoning about strengths, gaps, and overall fit. Feedback such as Yes, Maybe, or No is intended to refine subsequent reviews. The provider documentation lists direct integrations with several common ATS platforms.
This is useful when recruiters first need to organize a large document queue. The limitation remains the source material: missing evidence in a resume is not the same as a missing skill. Test whether inconclusive cases remain visible, whether criteria can be revised, and whether the system can trigger a follow-up question instead of a silent rejection.
3. Sprad Atlas: resume review, chat and voice in one process
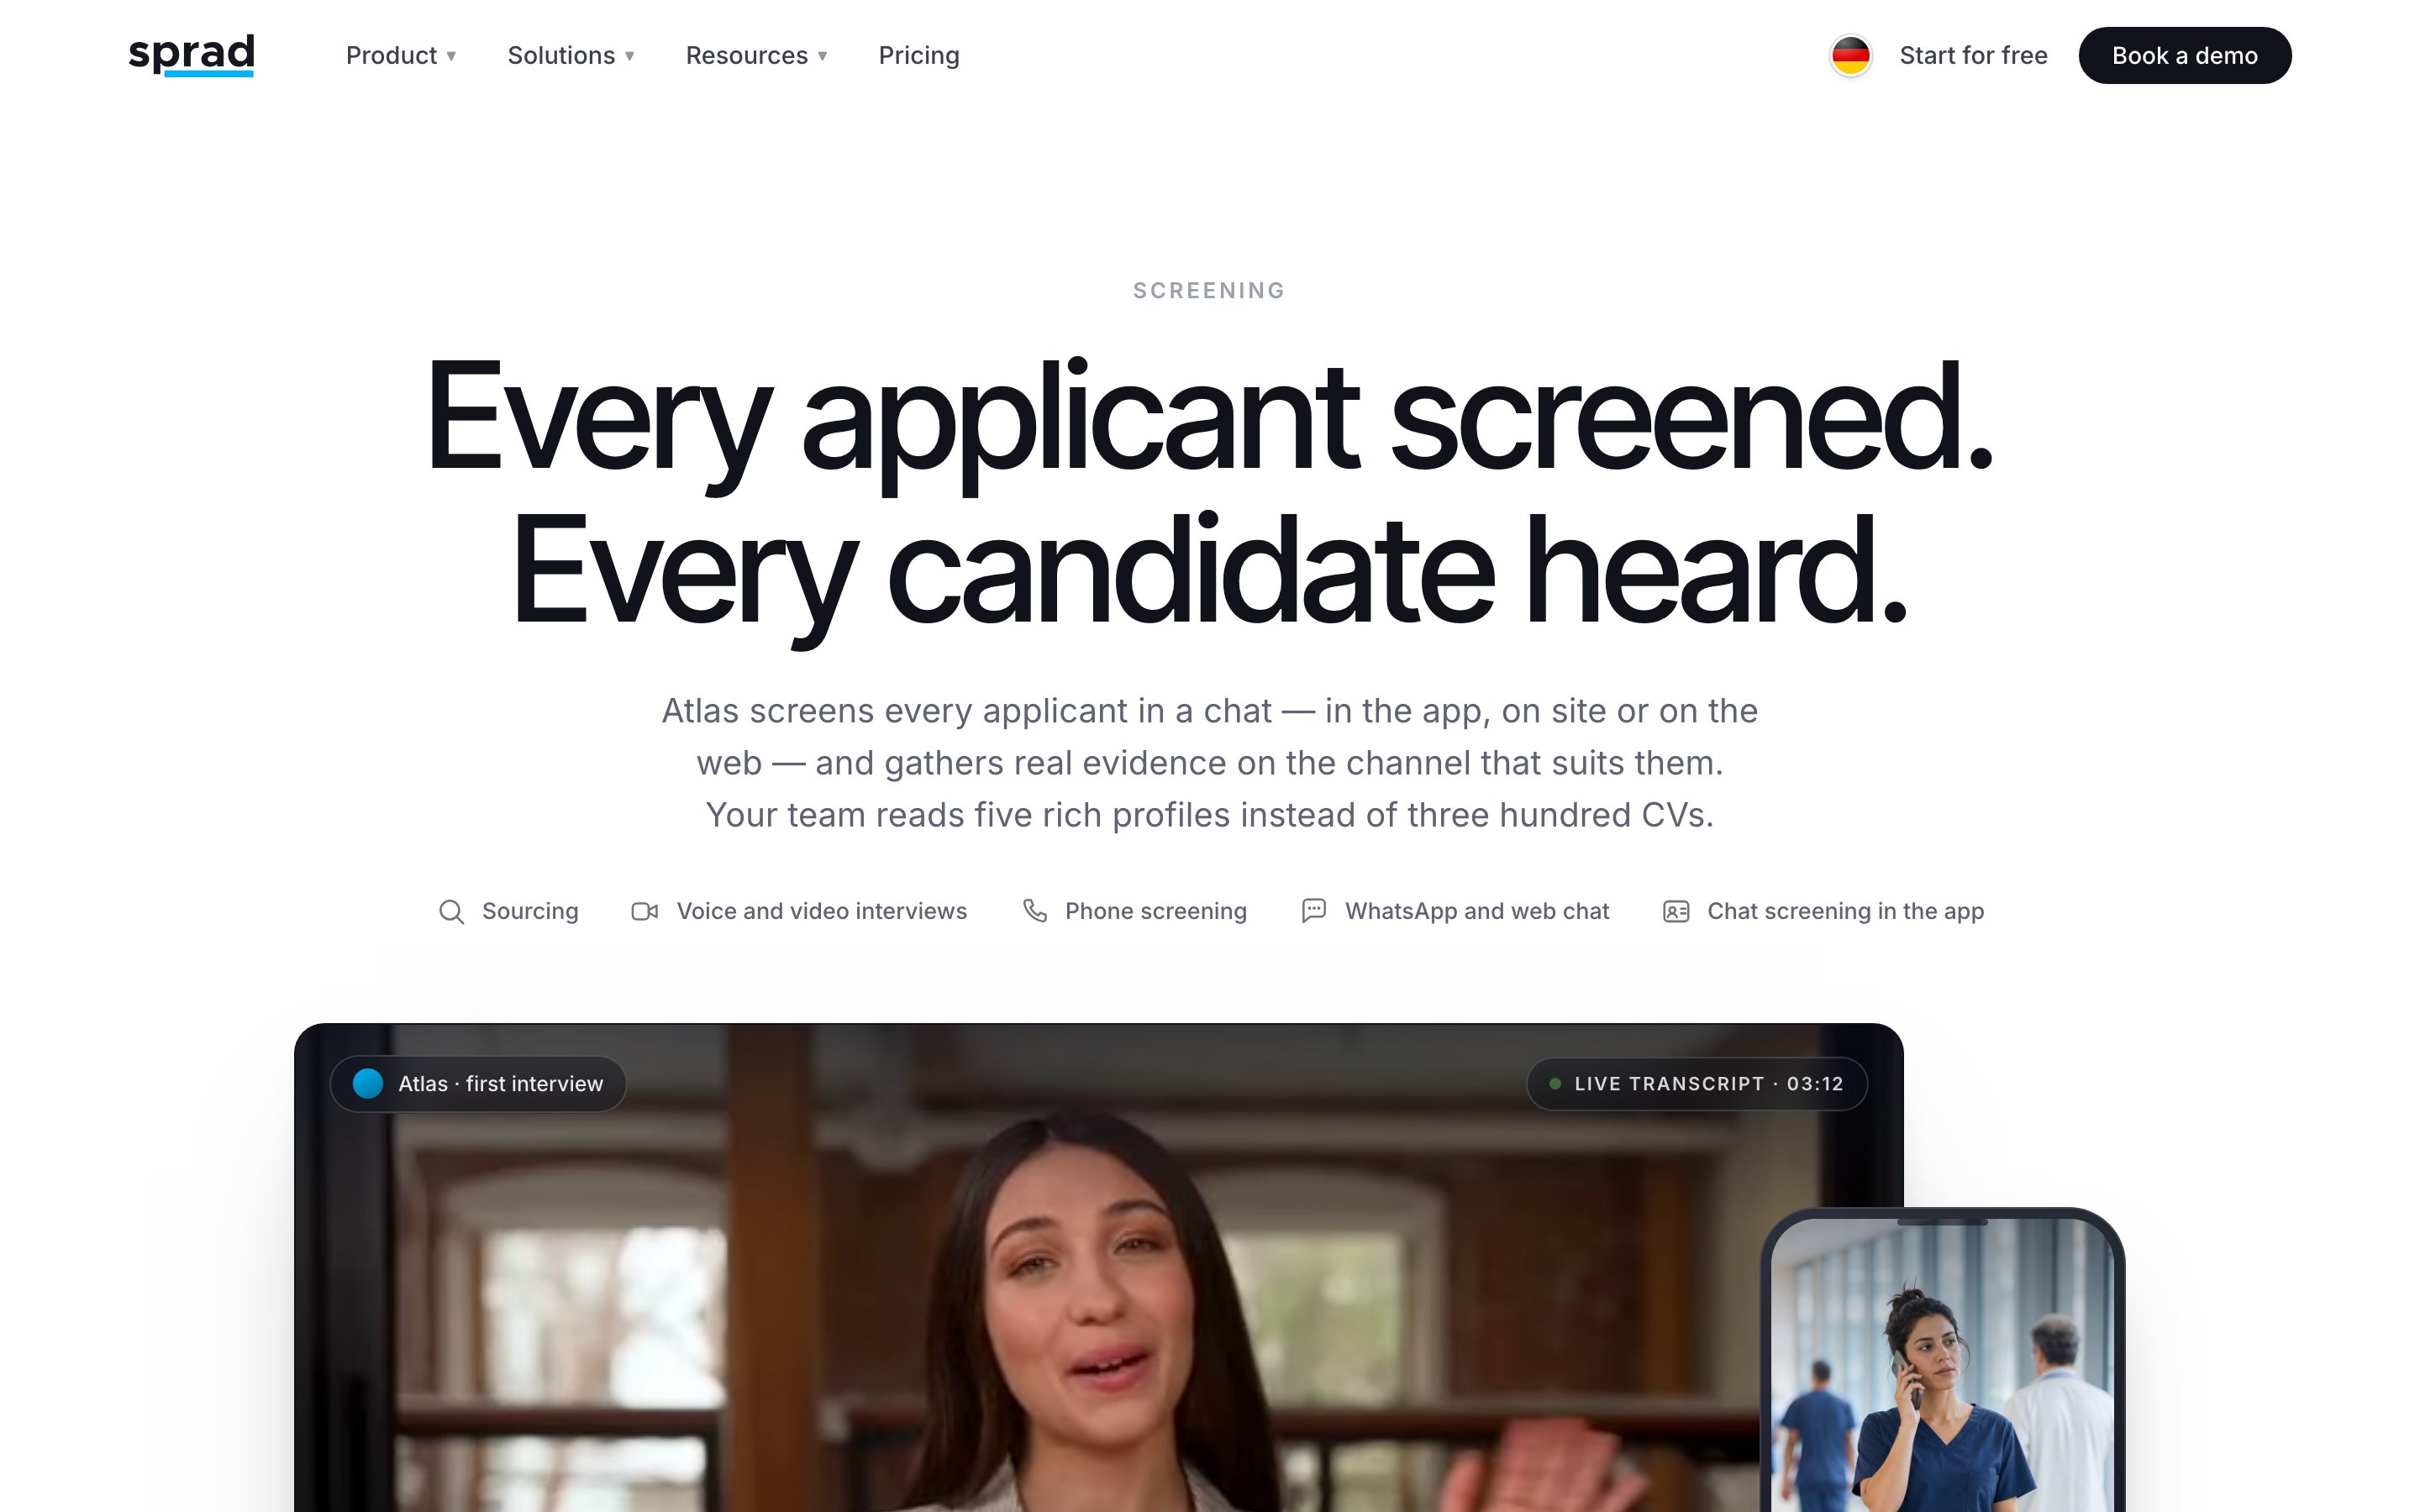
Sprad Atlas reads and rates every application against the criteria you define, with a reason for each criterion and the quote from the resume behind it. Nothing is rejected automatically; your team sees the evidence and decides. Where a resume lacks context, candidates can be invited to a chat, voice or video interview in many languages, or to a WhatsApp conversation. Results flow back into your existing applicant tracking system in both directions; Ashby, d.vinci and Personio are already connected, and any system with an API can be added.
Sprad is listed third because the order follows how close each tool sits to the existing ATS, not a score: for resume review inside the ATS, the ATS-native options come first. Sprad fits where resume evidence plus conversation in one record is the job, not every scenario. Four reasons you can check in a pilot:
- Evidence per criterion: every rating links to the answer or the passage it rests on, so a score is never the only output.
- Three signals, one record: resume, chat or voice interview and the candidate portal sit in one candidate record instead of three dashboards.
- Flat price per application: from 0.49 € per application (details in the cost section below), instead of quote-only pricing per module.
- Data handling: servers in Frankfurt (AWS), customer data never trains AI models, and no other customer sees your data.
Its breadth also creates the main test requirement: more signals only improve selection when each one answers a predefined question. A voice interview should clarify availability or elicit a work example, not judge personality. Sprad is also not a test library: for pure coding tasks or a large catalogue of skills tests, a specialist such as those below is leaner. In the US, text chat currently works best; phone and other channels need an individual setup.
Disclosure: This article is published by Sprad. We therefore do not present Sprad as an automatic winner. Test its evidence, failure cases, integrations and candidate alternatives against the same standard as every other provider.
Hard knockout rules can be automated regardless of vendor; our guide to automating knockout criteria shows how to do it without pre-filtering people out unlawfully.
4. TestGorilla: broad skills assessment
TestGorilla provides ready-made skills tests, custom questions, and AI-assisted interviews across many role areas. It is most relevant when you want to test specific knowledge or a work situation before the first live conversation, rather than relying on self-reported experience.
A large library does not make the selection decision for you. A test can be technically sound yet too long, too general, or too early for your role. Include only tasks whose result a subject-matter expert can explain. Also test abandonment, mobile use, accessibility, and the process for reasonable adjustments.
5. HackerRank: deeper technical screening
HackerRank focuses on developer roles. Prebuilt job-related assessments, custom tasks, leaked-question protection, and technical interview environments help teams evaluate programming ability closer to real work. That is a clearer signal than searching resumes for technology names.
The platform is not a general-purpose tool for nontechnical hiring. Even for developers, a coding result does not fully represent communication, product judgment, or collaboration. A sound process uses the assessment as evidence for defined technical skills and develops the later specialist interview from it.
6. HireVue: an assessment suite for standardized programs
HireVue combines structured video interviews with simulations, technical tasks, language tests, and other assessment methods. This breadth suits large selection programs that need to manage different job families consistently on one platform.
Breadth requires setup. Determine which modules are actually necessary for the role, how scoring models are validated, and where human review occurs. Do not test the experience only with confident internal users. Video, game mechanics, or longer assessments can introduce different barriers for different candidate groups.
7. Paradox: conversational screening for high volume
Paradox guides candidates through applications, initial job-related questions, and scheduling by text or chat. A mobile entry through QR code or text is particularly relevant for frontline roles where a long desktop form creates unnecessary friction.
The method is strong for explicit conditions such as location, work authorization, shift patterns, or availability. It becomes weaker when a complex competency is inferred from a few yes-or-no questions. Document which response simply routes a person forward, which triggers clarification, and when a human takes over.
8. Willo: asynchronous structured responses
Willo lets teams create structured questions and assessments that candidates complete later through video, audio, or other response formats. Transcripts, summaries, and job-related insights support subsequent human review. This can make recurring screening conversations more flexible.
Asynchronous does not automatically mean accessible. Some roles are better demonstrated in a work sample than on camera; some candidate groups prefer phone or text. Check that candidates understand the purpose, can get technical help, and may use an alternative channel without penalty. Evaluate the substance of a response, not presentation or production quality.
What does candidate screening software cost?
Prices in this category are built differently: per test, per interview, per seat, per application or per contract. The only fair comparison is the same pilot scope quoted by every vendor. For Sprad the list prices are public (sprad.io/pricing, as of 29 October 2026, excl. VAT, billed annually):
| Module | Price per application | What is included |
|---|---|---|
| Base | 0.49 € | CV screening, chat interviews, candidate portal |
| + Voice | +0.20 € | Voice interview for every fifth application |
| + Video | +0.60 € | Video interview for every tenth application |
Over 30,000 applications a year, an enterprise price per application applies. Anything beyond the booked volume runs on credits. There is also a pay-per-use route: the free plan includes 100 credits a month, and a resume check costs 2 credits per application, which is about 50 checks a month at no charge.
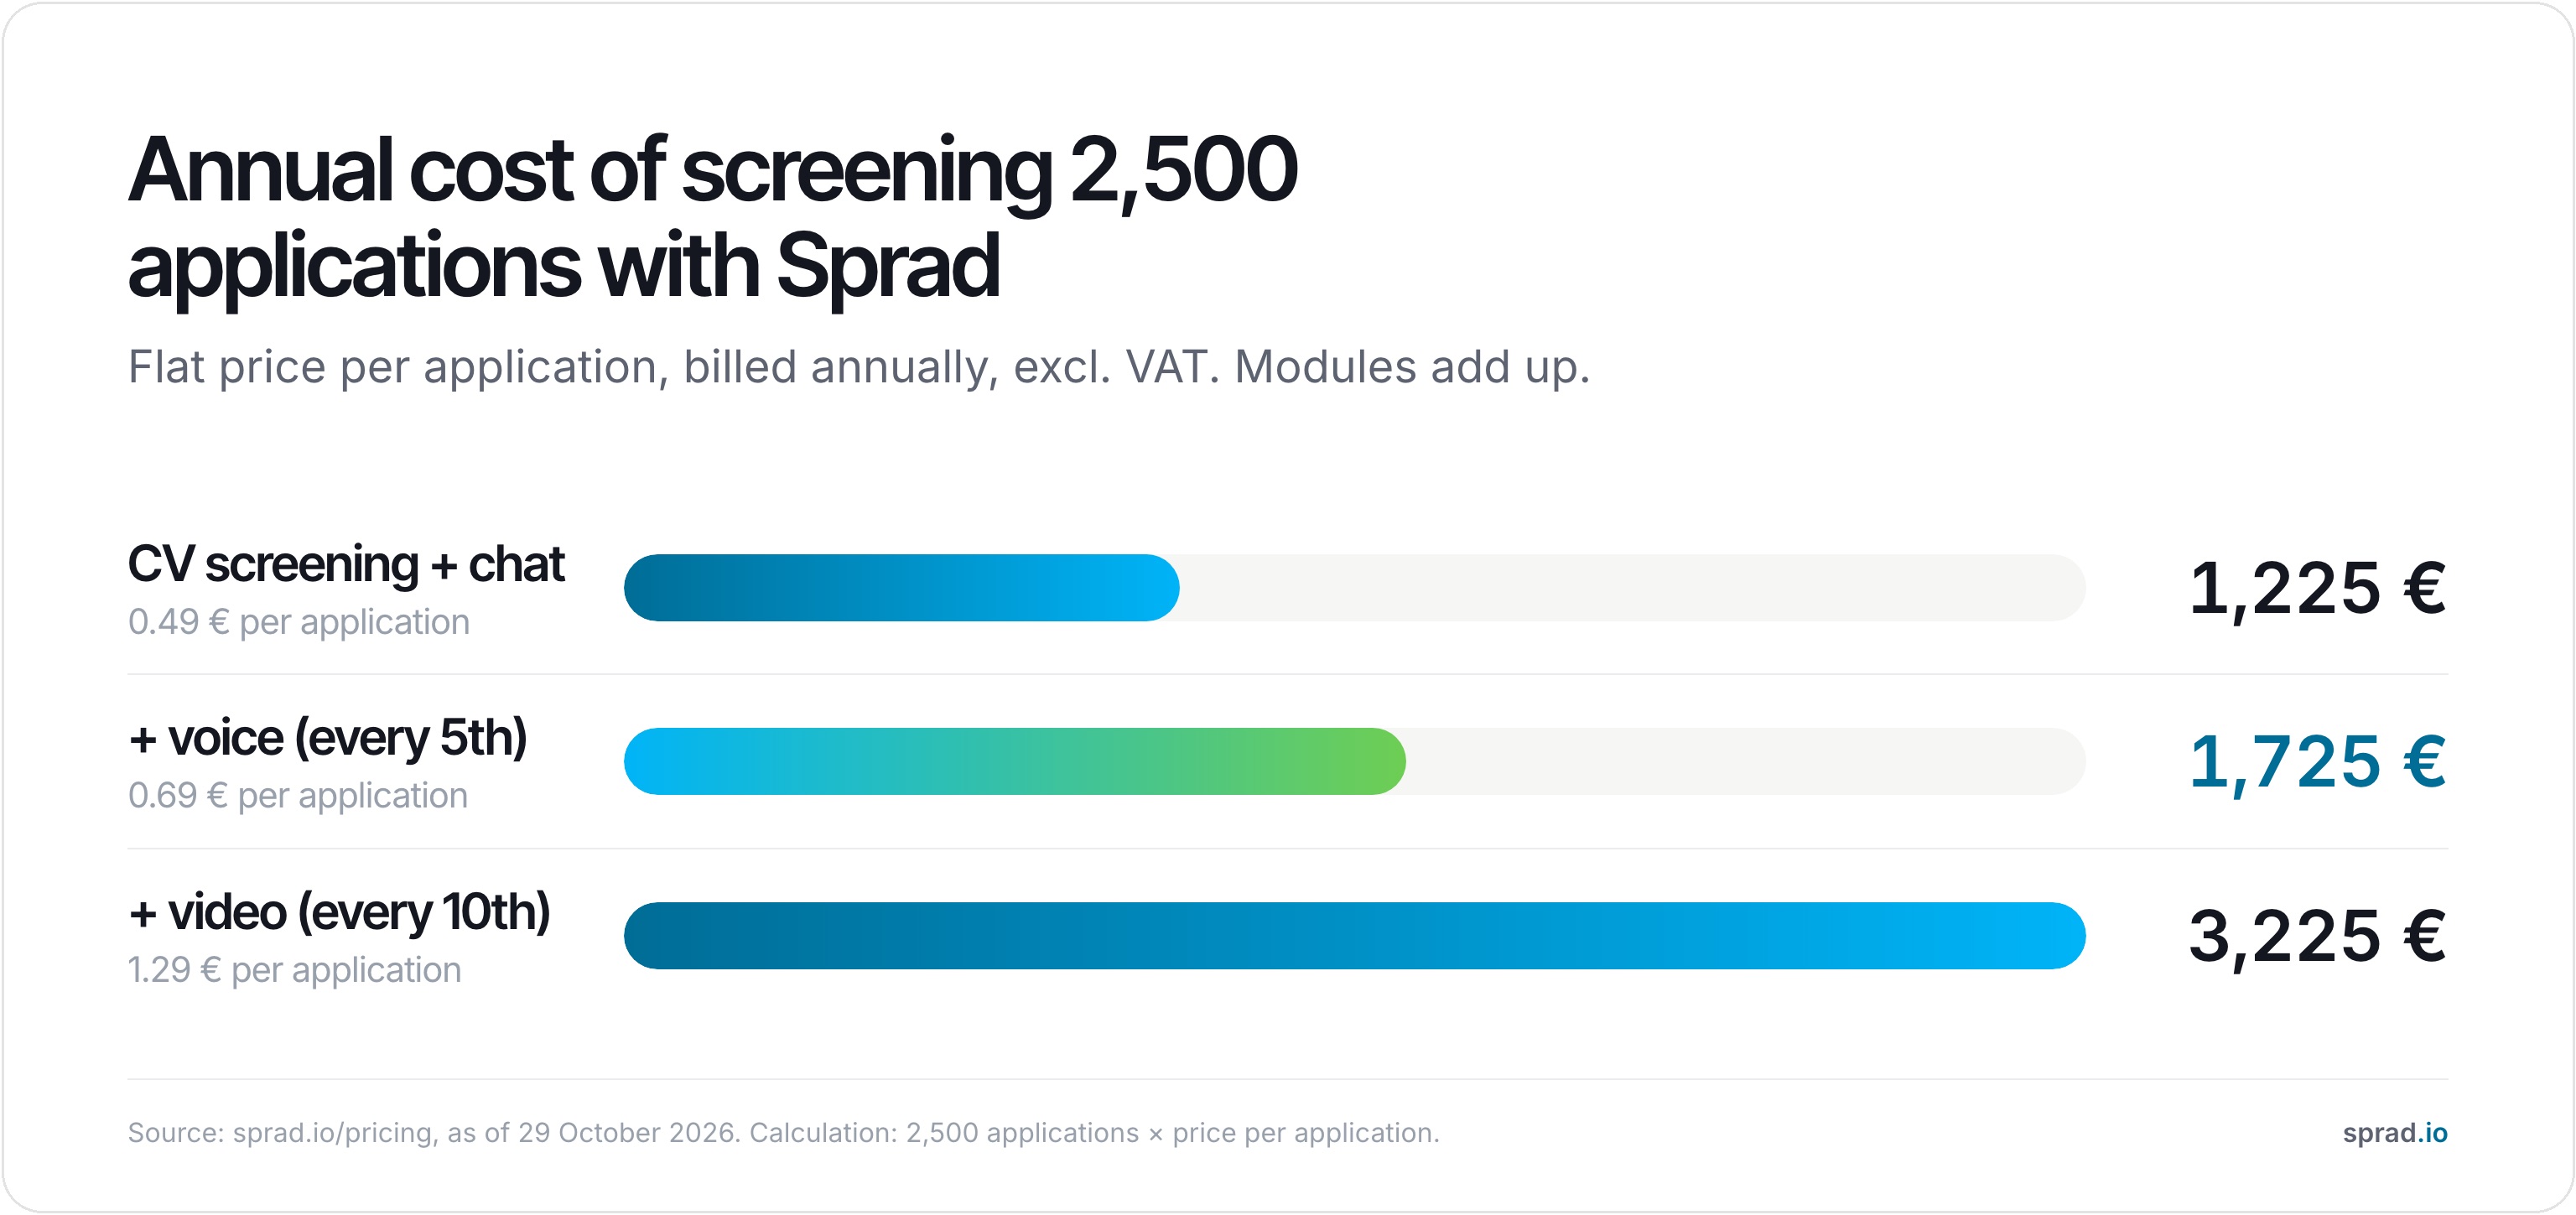
Worked example (our assumption): A company receives 2,500 applications a year. If a recruiter needs six minutes to read one resume and note a decision, that is 250 hours of first-pass review. At a loaded cost of 40 € per hour this is 10,000 €, against 1,725 € a year for base plus voice screening (2,500 × 0.69 €). The six minutes and the hourly rate are assumptions; replace them with your own figures. The real saving also depends on how many applications still need a human read, because the evidence replaces the first pass, not the decision.
Which tool fits each screening problem?
Start with the missing evidence, not a vendor list. The following matrix is a pilot shortlist, not a ranking. A provider advances only if it produces the specific signal with less friction and better traceability than your current process.
| Your bottleneck | Natural shortlist | What the pilot must prove |
|---|---|---|
| Review many resumes against explicit requirements | Sprad, Greenhouse, Metaview | Reasoning matches source documents and inconclusive cases remain visible |
| Test technical ability before an interview | HackerRank | Tasks resemble the actual work and produce useful follow-up questions |
| Assess broad skills across job families | TestGorilla, HireVue | The test package is job-related, proportionate, and interpretable |
| Qualify frontline applicants on mobile devices | Paradox, Sprad Voice | The entry works on the preferred device and complex cases are handed off |
| Collect structured responses asynchronously | Willo, HireVue | The response format improves evidence without unnecessary barriers |
| Connect resume and conversation context | Sprad | Signals remain distinct and write back cleanly to the ATS |
If you are not yet sure whether the missing signal is document-based or spoken, the guide to AI interviews and voice recruiting explains where conversational screening belongs. For buying purposes, it is not enough to ask whether a feature exists. Ask exactly where it produces a verifiable information gain.
How to run a reliable software pilot
- Define the decision: Write down the decision that follows screening and the criteria needed to make it.
- Define the evidence: Assign an appropriate source to every criterion: resume passage, work sample, structured answer, or confirmed minimum requirement.
- Include edge cases: Use incomplete, unusually worded, and accessibility-related cases alongside obvious matches and nonmatches.
- Review independently: Have recruiting and the hiring team evaluate outputs separately at first. Then compare the reasoning, not only the scores.
- Test ATS write-back: Check status, fields, evidence, corrections, deletion, and export. A PDF report in a second dashboard is not yet an integration.
- Include candidates: Ask about clarity, effort, technical access, and the perceived connection to the job.
- Set operating rules: Name owners, review samples, change approvals, and the path for challenges or corrections.
For conversational products, deepen the test with the criteria in the guide to AI voice interviews. The complete chain matters: criterion, question, response, and visible reasoning in the ATS.
Typical mistakes in screening pilots
- Testing only clear cases: every tool looks good on obvious matches. Include incomplete, oddly worded and borderline profiles.
- Vague criteria: "team player" cannot be traced to a resume passage. Write criteria a reviewer could verify in the source.
- Pilot too small: fewer than 50 real applications hides failure cases. Use one open role with real volume.
- Trusting the score: check whether the output changes sensibly when you change one relevant detail in a resume.
- Forgetting the candidate: measure drop-off, mobile completion and the number of people who ask for an alternative channel.
Data protection, the EU AI Act, and worker representation
Screening software processes information in a sensitive decision context. Annex III of the EU AI Act lists systems intended for recruitment and selection, in particular to analyze and filter job applications and to evaluate candidates, among its high-risk use cases. Following the Digital Omnibus, Regulation (EU) 2026/1744 (in force since 27 July 2026) moved the high-risk obligations for these systems to 2 December 2027. Transparency duties under Article 50, such as telling people they are interacting with an AI system, apply from 2 August 2026, which matters for every voice or chat interview. The ban on inferring emotions in the workplace (Article 5, in force since 2 February 2025) is a reason to avoid vendors that score voice or facial emotion. Which duties apply to your system should be assessed by qualified advisers before deployment.
In addition, Article 22 of the GDPR restricts solely automated decisions that produce legal or similarly significant effects and sets out limited exceptions with safeguards. In practice, human review must be more than a sentence in the privacy notice: the reviewer needs to understand the evidence, correct errors and genuinely override the recommendation. In Germany, the General Equal Treatment Act (AGG) also applies to selection; if there are indications of discrimination, the employer has to prove otherwise (section 22), so a documented evidence trail protects you.
Also, section 87 of the Works Constitution Act addresses co-determination for technical devices designed to monitor employee behavior or performance. Whether and how it applies depends on the actual deployment. Involve privacy, security and worker representatives early. The guide to works council involvement in AI recruiting provides a fuller orientation. This is not legal advice.
Warning signs when selecting a provider
- A score without a source: The system shows a number but not the answer, passage, or task behind it.
- Generic fit: One universal suitability score replaces clearly named essential and desirable criteria.
- Hidden rejection: Low-rated profiles disappear before a person can review borderline cases.
- No alternative: Video, speech, or a specific device is mandatory even though the job does not require it.
- Integration means download: Results arrive only as an attachment and cannot be searched or corrected in the ATS.
- Unclear data flows: Retention, training use, subprocessors, export, and deletion remain unanswered.
- Demo instead of pilot: The vendor shows only polished sample profiles and avoids your real roles and failure cases.
Verdict: buy the evidence, not the ranking
Candidate screening software is valuable when it answers a concrete selection question better than your current process. Sprad, Greenhouse, and Metaview are natural candidates for resume prioritization. HackerRank is focused on technical depth. TestGorilla and HireVue cover broader assessments. Paradox fits mobile, high-volume qualification, while Willo focuses on asynchronous structured responses.
The shortlist is only the beginning. Require job-related criteria, visible evidence, realistic edge cases, working ATS write-back, and a genuine human decision in the pilot. The best tool is not the one with the longest feature list. It is the one whose outputs your team can explain and take responsibility for.
Frequently asked questions about candidate screening software
What is the difference between an ATS and screening software?
An ATS manages jobs, applications, communication, and workflow stages. Screening software creates or organizes evidence for early selection from sources such as resumes, tests, or structured responses. Some ATS products include screening features, while specialist tools often connect to an existing ATS.
Can candidate screening software reject applicants automatically?
Systems can technically apply rules and thresholds. A solely automated rejection is legally and professionally sensitive, however. Design the process so qualified people can see the reasons, review borderline cases, correct errors, and effectively change decisions. Obtain legal advice for the actual deployment.
What candidate screening software is best for a small team?
Small teams usually benefit from a tightly scoped product that solves their largest bottleneck and writes results back without parallel data entry. Do not automatically choose the broadest suite. A short, job-specific pilot will show whether a specialist assessment, resume review, or structured conversation is enough.
How do you test the quality of an AI ranking?
Compare the reasoning with the original source. Include clear matches, clear nonmatches, and ambiguous profiles. Then change one relevant detail and check whether the output responds plausibly. A stable score without a sensible change in evidence is not proof of quality.
How much screening should be automated?
Automate recurring data collection, structuring, and prioritization. Keep criterion design, exceptions, borderline cases, and next-step decisions with people. The more strongly a tool evaluates or excludes candidates, the more important traceability and oversight become.
Does screening software replace the recruiter interview?
It can collect information that would otherwise require many similar first calls. It does not replace a two-way conversation about the role, expectations, collaboration, and candidate questions. Good screening software prepares that discussion and makes it more focused.
How much does candidate screening software cost?
It depends on the pricing model. Sprad charges per application: 0.49 € for CV screening, chat interviews and candidate portal, 0.69 € with voice interviews for every fifth application (list prices, as of 29 October 2026, excl. VAT). For 2,500 applications a year that is 1,725 €. Many other vendors price per seat, test or contract, so ask each for a quote on the same pilot scope.
Is candidate screening software allowed under the EU AI Act?
Yes, but it is a high-risk use case under Annex III. The high-risk obligations apply from 2 December 2027 (Regulation (EU) 2026/1744); transparency duties for AI interactions apply from 2 August 2026. Choose tools that support human oversight, documentation and a visible evidence chain now, rather than retrofitting them later.
How long does it take to set up a pilot?
As a rule of thumb, plan two to four weeks for one open role: define the criteria, connect the ATS, run 50 to 100 real applications through the tool in parallel to your current process and compare. This is our recommendation, not a vendor promise.
Can AI screening discriminate against candidates?
It can, if criteria or training data encode bias, and a stable score is no proof of fairness. Reduce the risk with job-related criteria, evidence you can read, regular samples reviewed by people, an alternative channel for candidates and a documented process for corrections.
Jürgen Ulbrich
Jürgen Ulbrich has more than a decade of experience in developing and leading high-performing teams and companies. As an expert in employee referral programs as well as feedback and performance processes, Jürgen has helped over 100 organizations optimize their talent acquisition and development strategies.